The five things that have to be true underneath
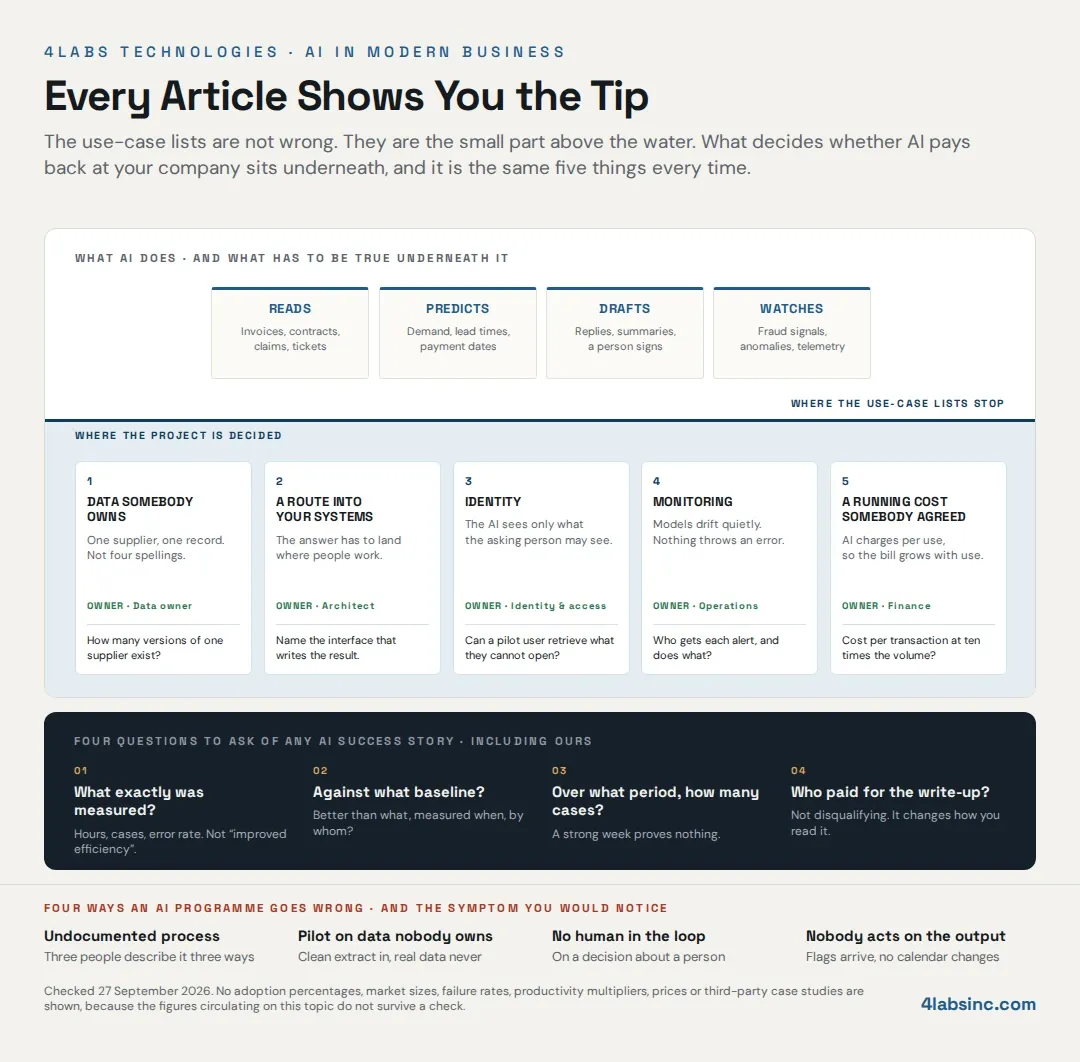
None of these is exciting, and all five decide whether the impact of AI on modern business shows up in your business or only in the slide deck. Each one closes with an owner and a test you can run this week.
One: data somebody owns
Every prediction, suggestion and extracted field lands against a record: a customer, a material, a supplier, a patient or a claim. If those records are inconsistent, everything built on them inherits the inconsistency and nobody sees it happen.
The test takes ten minutes: pick one supplier and count how many versions of it exist across your systems. More than one, and a model will treat them as different suppliers, so your forecast will be wrong in a way no dashboard reveals.
Fixing this is not an AI project but master data work: naming a person per core record type who decides what the fields mean and who may create new ones. That work transfers to every future system, which is why it is worth doing before rather than during. Our posts on AI and machine learning in data management and on data management and governance cover both halves of it.
Owner: a business data owner per record type. Test: can somebody name who approves a new supplier record?
Two: a route into the systems of record
An answer nobody can act on inside the tool they already use is a demo, not AI implementation.
The question is concrete. When the model reads the invoice, what writes the result into the finance system; when it flags the anomaly, where does the flag appear; and when it drafts the reply, what sends it?
If the honest answer to any of those is that somebody copies it across, the pilot will work and the rollout will not, because copying is fine for twenty a day and impossible at two thousand, and the volume is exactly what the project was supposed to fix.
Decide the route before the pilot: an API, a middleware layer, an event stream, or a queue somebody owns. Business process automation succeeds or fails on this single point more than on any model decision.
Owner: integration architect. Test: name the interface that writes the output into the system of record.
Three: identity, so the AI sees only what the person may see
This one arrives in week three of every enterprise pilot and surprises people every time.
An assistant that answers questions over company documents has to respect the same permissions as the person asking. Otherwise a helpful summary hands a salary band, a board paper or an unannounced redundancy to somebody who could not have opened the file.
The fix is not a setting: it means the AI queries on behalf of the user rather than with its own blanket access, and that has to be designed in, because retrofitting it is a rebuild.
Decide two things early: whose identity the system acts under, and what happens to documents whose permissions are wrong today. Most enterprises have a shared drive that would embarrass them, and AI does not create that problem, it finds it.
Owner: identity and access, with the security team. Test: ask whether a pilot user can retrieve something they could not open directly.
Four: monitoring, because models drift quietly
Software that breaks throws an error, while a model that degrades keeps answering, in the same tone, with the same confidence, and slowly gets worse.
Your supplier base changes. A product line launches. A process is redesigned. The pattern the model learned stops matching the world it runs in, and nothing alerts anybody. People notice months later, usually because somebody senior spots an answer that is obviously wrong.
Model drift is the name for it, and it means somebody has to decide what you watch: the share of cases sent to a human, how often a person overrides the suggestion, how answer quality on a fixed set of test cases moves month to month, and latency and cost per call, which are infrastructure signals that a change has happened upstream.
Then decide who receives each signal, by name. This is ordinary operations work, and it belongs with whoever already watches your estate. If a network operations centre watches your infrastructure, AI monitoring belongs on the same wall, not in a data-science notebook nobody opens.
Owner: operations, with the team that built the model. Test: for each signal, who gets the alert and what do they do?
Five: a running cost somebody has agreed to
This is the item that surprises finance, and it is an AI infrastructure question rather than a software one.
Traditional enterprise software costs what the licence costs. AI costs per use. Every document read, every question asked, every summary drafted has a cost attached, and that cost scales with adoption, so a pilot with forty users tells you very little about a rollout to four thousand.
There are no prices in this article, because they change and because yours depend on your volumes and your deployment. What matters is asking the right shape of question before you commit.
Four questions cover it. What does one transaction cost to process today? What will it cost through the AI path? How does that change at ten times the volume? And who signs for the difference?
The deployment choice sits underneath all four, because where the workload runs decides most of the bill. Our posts on cloud or on-premises and building a scalable IT infrastructure cover that decision properly.
Owner: finance, with the infrastructure lead. Test: can somebody state the cost per transaction at ten times current volume?