Every list of RPA implementation challenges says roughly the same thing, and all of it is true. Process selection, resistance to change, scalability, governance, security, maintenance. If you have read one of those lists you have read all of them, and you almost certainly finished no better placed than when you started.
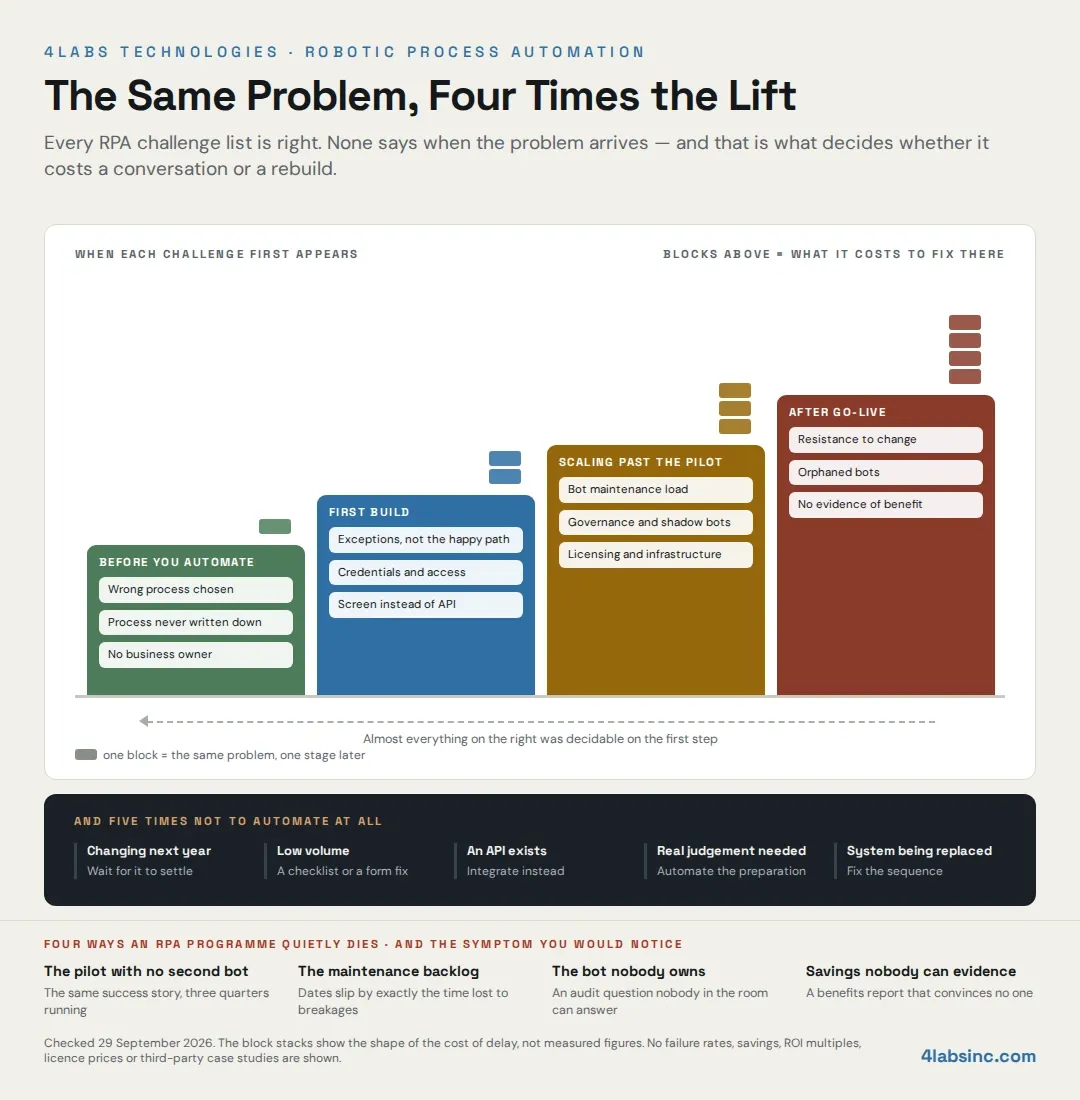
The missing piece is timing. A challenge you meet before anything is built costs a conversation to fix, while the same challenge met after twenty bots are in production costs a rebuild and a difficult meeting. Knowing which problems arrive when is what turns a list into a plan, and it is the reason two organisations running identical automation platforms end up in completely different places.
So this page sorts the challenges by the stage they show up in: before you automate anything, during the first build, when you scale past the pilot, and after go-live. Each one gets what it looks like from the inside, why it happens, what to do about it now, and what would have prevented it. There is also a section most pages on this subject avoid, which is when RPA is the wrong tool and you should not automate at all.
You will not find a failure-rate percentage here, or a savings multiple. Both are quoted on nearly every page about RPA and attributed on almost none, and if you are reading this because a promised number did not materialise, another one is the last thing you need.
We do this work for enterprise clients as part of our RPA automation services, including picking up estates that stalled after a pilot. If you are earlier in the subject than this page assumes, our introduction to robotic process automation covers the basics first.
What makes RPA implementation different from ordinary software projects
RPA gets treated as a normal software delivery, and that assumption is behind a surprising number of the problems below. A bot is software whose dependencies are other people's software, accessed the way a person would access it, with no contract governing any of it.
When you integrate two systems through an API, there is a version, a deprecation policy and usually somebody to email. When a bot drives a screen, there is none of that. The finance team's supplier portal gets a new layout on a Tuesday, nobody tells you, and your bot spends the rest of the week putting invoice numbers into the wrong field.
That single difference shapes everything else, and it is worth holding in mind as you read the four stages.
Why RPA projects fail in ways other software does not
Three reasons, and none of them is about the technology being immature.
The first is that bots fail quietly. Conventional software that breaks throws an error and somebody notices within minutes. A bot that breaks often carries on running, because from its point of view nothing failed — it clicked where it was told to click. The damage is discovered later, by somebody reconciling the numbers, and by then it has been happening for a fortnight.
The second is that the dependency is invisible to the people who control it. Nobody in the team that upgraded the portal knows a bot depends on it, because that dependency is not written anywhere a change manager would look. Ordinary integrations appear in architecture diagrams, and screen-level automation rarely does.
The third is that RPA is bought as a project and lives as an operation. The business case covers building the bot. Nothing in it covers the three years afterwards, when every system the bot touches keeps changing and somebody has to keep up.
Attended and unattended bots, and where each one bites
The two models fail differently, and it is worth being clear which you are running.
An attended bot runs on a person's desktop while they work, usually triggered by them. It inherits their machine, their session, their permissions and their interruptions. It is quick to deploy and hard to govern, because as far as every other system is concerned the person did it. When something goes wrong there is no clean audit trail separating the bot's actions from the person's.
An unattended bot runs on its own, on a schedule or a queue, on its own machine. It needs its own identity, its own credentials and somewhere to run, which is more setup and much better hygiene. It also needs somebody to watch it, because when it stops at two in the morning nobody is sitting in front of it.
Stage one: RPA implementation challenges before you automate anything
Nothing has been built yet, which makes this the cheapest stage to get things right and the one organisations move through fastest. Every problem here costs a conversation now and a rebuild later.
Choosing the wrong process
The most expensive mistake in RPA, and it happens in week one.
What it looks like: a bot that works, that nobody misses when it is switched off. Or one that took three months to build for a process that runs forty times a year.
Why it happens: the first process is usually chosen because somebody complained loudly about it, or because it demonstrates well. Neither is a measure of value. A process that is painful is not automatically a process that is worth automating, and the two get conflated in the enthusiasm of a pilot.
What to do now: rank your candidate processes by volume multiplied by stability, and ignore the loudest voice. A boring high-volume process with unchanging rules beats an interesting one every time.
What prevents it next time: a standing selection test that anybody can apply, which is below. Our note on how RPA is transforming business processes covers the shapes of work that suit automation in more depth.
Automating a process nobody has written down
What it looks like: the bot goes live and immediately hits cases the team handles daily but never mentioned, because to them those cases are not exceptions, they are just Tuesday.
Why it happens: four people do the process four ways. The version you documented is whichever person you sat with, and they described what they are supposed to do rather than what they do. Nobody was hiding anything; the variation is invisible from inside it.
What to do now: watch the work rather than asking about it, and watch more than one person. If a process mining or task mining tool is available, use it, because it shows the paths people actually take rather than the one they remember. Then write the process down as a standard operating procedure and have the team correct it, which is where the real version surfaces.
What prevents it next time: treat the written process as a deliverable of its own, signed off before any bot is built. Automating an undocumented process means automating whichever version you happened to see.
No owner on the business side
What it looks like: IT builds the bot, IT deploys the bot, and when the bot does something wrong the conversation begins with everyone establishing that it was not their decision.
Why it happens: automation is bought as a technology initiative, so it gets a technology owner. But a bot enforces a business rule, and the person who can say what the rule should be does not work in IT.
Stage two: RPA implementation challenges during the first build
The process is chosen and somebody is building. The problems here are still cheap to fix, and they set the pattern every later bot will copy.
The happy path problem, and exception handling
What it looks like: the demo is flawless and the first week in production is not. The bot stops on cases nobody mentioned, and the team goes back to doing the work by hand while somebody investigates.
Why it happens: the bot was built against the path the process takes when everything is normal. Real queues contain the invoice with two purchase order numbers, the document somebody scanned upside down, the supplier whose name has a comma in it, and the record that is locked because a colleague has it open.
What to do now: work out what proportion of cases the bot can genuinely complete unassisted, and design the remainder deliberately. Every exception needs a decision: retry, route to a person with the context attached, or stop and alert. An exception with no defined route becomes a silent backlog.
What prevents it next time: build the exception path at the same time as the happy path, not afterwards. And accept publicly that a bot handling eighty per cent of cases cleanly is a good bot. Teams that promise to automate a process entirely end up with a bot that is switched off, because the last few cases are where all the complexity lives.
Credentials, service accounts and access
What it looks like: the bot runs under a named employee's login. Everything works. Then that person leaves, or their password rotates, and several bots stop at once.
Why it happens: giving the bot somebody's credentials is the fastest way to get a pilot moving, and nobody wants to open a request that takes three weeks.
What to do now: give each bot its own service account with only the permissions that bot needs, and store the credentials in the platform's vault rather than in the script. If a bot is currently using a person's login, treat that as the first thing to fix, because it is also the thing an auditor finds first.
What prevents it next time: make an identity request part of the build checklist, alongside the environment. This is also where automation meets infrastructure practice more generally, which our note on automation in IT infrastructure covers.
Building against a screen instead of an API
What it looks like: a bot that breaks every time an application is updated, and a developer who spends more time repairing selectors than building anything new.
Why it happens: the screen is always available and the API needs a request, a licence, or a conversation with a vendor. Screen scraping is what RPA is famous for, so it becomes the default rather than the fallback.
Stage three: RPA implementation challenges when you scale past the pilot
Scaling RPA is where most programmes stall, and the challenges here are different in kind rather than in degree. The pilot worked, the second and third bots went in, and somewhere around the tenth the whole thing starts to feel heavy.
Bot maintenance and the change you did not control
What it looks like: the automation team stops building. Their week is spent repairing bots that broke because an application changed, and the backlog of new automations has not moved in two months.
Why it happens: every bot is a standing commitment, and nothing in the original business case said so. Twenty bots touching a dozen applications means a dozen sources of change arriving on somebody else's schedule.
What to do now: count it honestly. List every bot, the applications it touches, and how often it has broken in the last quarter. That list usually shows two or three bots causing most of the pain, and the cheapest fix is often to retire the worst one rather than repair it again.
What prevents it next time: budget maintenance capacity as a percentage of the team from the first bot, and get the automation team onto the change-advisory list for every application they depend on. Most bot breakages are announced somewhere — just not to the people who needed to hear it.
Governance and who is allowed to build
What it looks like: nobody can say how many bots are running. A department built four on a desktop licence, two of them touch finance data, and they surfaced during an audit.
Why it happens: modern platforms are genuinely easy to build on, which is their selling point. Citizen developers build faster than the governance around them arrives, especially when central IT has a queue.
What to do now: build a register of every automation, who owns it, what it touches and what it is allowed to do. Then decide what people may build without approval and what requires review — a rule that is enforceable, because a blanket ban simply moves the activity out of sight.
What prevents it next time: publish the rule before the platform spreads. Two tiers is usually enough: personal productivity automations that touch nothing shared, and anything touching a system of record, which goes through review.
Licensing, orchestration and infrastructure cost
What it looks like: the renewal quote arrives and it is not what anybody expected, or a bot cannot run because all the runtime licences are in use during the month-end peak.
Why it happens: the licence model that was cheap at three bots scales differently at thirty. Unattended runtimes, orchestrator capacity, the machines the bots run on, and the environments you need for testing all grow with the estate, and only the first of those usually appears in the original case. The models differ between UiPath, Automation Anywhere, Blue Prism and Power Automate, so the shape of the bill depends on which platform you picked.
Stage four: RPA implementation challenges after go-live
The bots are running. These challenges decide whether the programme is still running in two years.
Resistance to change, and what people are actually worried about
What it looks like: the team finds reasons the bot cannot be trusted. Cases get routed around it. Somebody keeps doing the work manually in parallel, just in case.
Why it happens, and this is the part most change management advice misses: people are rarely resisting the technology. They are worried about three specific things. Whether their job still exists. Whether their appraisal now measures something they no longer control. And whether they will be blamed when the bot gets something wrong, since their name is still on the process.
What to do now: answer those three questions directly and early, in plain words, including the uncomfortable one. If roles will change, say how. If nobody is being let go, say that clearly, because in the absence of a statement people assume the worst. Then make the same team the owners of the exception queue, so the bot is a tool they direct rather than a replacement watching them.
What prevents it next time: involve the people who do the work in the selection and the design. The team who chose which parts to automate do not resist the result, and they know where the awkward cases hide, which improves the bot as well.
Orphaned bots and the person who left
What it looks like: a bot running in production that nobody can explain. It touches finance data, the developer left last year, and the documentation is a diagram in a deck.
Why it happens: bots get built under pressure, documentation is the step that gets cut, and knowledge lives with individuals rather than in the register.
What to do now: for each bot, write down what it does in business terms, what it touches, what happens when it fails, and who to call. One page each. If a bot cannot be explained at all, switch it off in a controlled way and see who complains — an unowned bot touching a system of record is a risk that will eventually be found by somebody other than you.
What prevents it next time: make that one-pager a condition of going live, and review ownership quarterly. People move roles; the register has to move with them.
Measuring whether it worked
What it looks like: a steering meeting where nobody can evidence the benefit, the original business case is quoted back, and the programme loses its budget in the next cycle.
Why it happens: the benefit was expressed as hours saved, and hours saved is the most disputed number in automation. Nobody left, so the cost did not fall, and the finance business partner is right to ask where the saving went.
RPA implementation challenges and solutions at a glance
The same list as above, in one place, with the stage each challenge first appears in.
| Challenge | Stage it appears | What it looks like | The solution in one line |
|---|---|---|---|
| Choosing the wrong process | Before you automate | A bot nobody misses when it is switched off | Rank candidates by volume multiplied by stability, not by who complained |
| Undocumented process | Before you automate | The bot meets cases the team handles but never mentioned | Watch several people work, write the process down, have the team correct it |
When RPA is the wrong tool
A challenges page that never concludes do not automate this one is a sales page with a problem-shaped introduction. Five signals, and each has a better answer than a bot.
The process changes next year. A migration is planned, the department is being reorganised, or the rules are under review. A bot built against a moving target spends its life being rebuilt. Wait, and automate the version that settles.
The volume is low. A few dozen runs a year will not repay the build and the years of maintenance behind it. Better answers: a checklist, a template, or a small change to the form that removes the work. Not everything inefficient is worth automating.
An interface already exists. If the systems can talk to each other directly, integration is cheaper to run and far more stable than a bot driving two screens. RPA earns its place where no interface exists and none is coming. Where one does exist, use it.
The judgement is real. If the decision depends on context a person holds — whether this customer is worth an exception, whether this claim smells wrong — then automation can gather the evidence and present it, and the decision stays with the person. Automating the preparation is valuable. Automating the judgement produces consistent decisions that are consistently wrong when the situation is unusual.
The underlying system is being replaced. Automating around a system due for replacement builds a dependency on something scheduled to disappear, and the bot becomes an argument for keeping the old system. Fix the sequence rather than the symptom.
There is a sixth case, and it is the most common one in practice. Sometimes the process should not exist. Several steps are there because a form was badly designed, or because two teams each verify the same thing. Automating that is faster wrongness. The cheapest automation is the one you avoid by deleting the work, and process discovery often surfaces these before anybody writes a line of code. Our note on future trends in robotic process automation covers where this is heading as automation and intelligent document processing converge.
Four ways an RPA programme quietly dies
None of these is an incident. Each is a slow fade, and each has a symptom you would notice months before anybody says the programme is over.
The pilot that never becomes a second bot. One automation goes live, it works, and then nothing else ships. The symptom is a steering meeting where the same success story is presented for the third quarter running. Usually the cause is that the pilot was built by somebody borrowed from another team, and nobody funded the capability afterwards. A pilot is meant to prove the approach, and if there is no plan for the second and third bot before the first goes live, there will not be one.
The maintenance backlog. New development stops because the team is repairing what exists. The symptom is a delivery plan where the dates keep moving by exactly the amount of time lost to breakages. Left alone this is terminal, because the programme stops producing anything new while still costing what it costs. The fix is unpopular and works: retire the worst bots rather than repairing them again, and rebuild the survivors on stable interfaces.
The bot nobody owns. An automation runs for months after its owner changed roles. The symptom is a question in an audit that nobody in the room can answer. Bots are not like documents; an unowned one keeps acting on live systems. Quarterly ownership review is dull and it is the whole fix.
The savings nobody can evidence. The programme is asked to justify itself, the original case promised hours saved, headcount did not change, and there is no baseline to compare anything against. The symptom is a request for a benefits report that takes three weeks to produce and convinces nobody. This kills more programmes than technical failure does, and where the shortfall is capacity rather than intent, staff augmentation for transformation projects is a more honest answer than another platform evaluation.
All four are governance and ownership failures rather than technology ones. The bots mostly work, and what fails is the arrangement around them — which is free to set up at the start and expensive to retrofit once there are thirty automations and no register.
Get your RPA implementation unstuck with 4Labs Technologies
If you recognised your programme somewhere in the last three sections, you are in the most common position there is. A pilot that worked, a handful of bots in production, and a feeling that adding the next ten would make things worse rather than better.
We look at what exists rather than starting with a platform recommendation. Which bots are worth keeping, which should be retired, which processes need redesigning before they are automated again, and what the operating model has to look like at the volume you actually want.
Work with our RPA automation services team
An engagement starts with the estate as it is. The list of automations in production, what each one touches, how often each fails, who repairs them, and what the original business case said. That last item is usually the most revealing, because the distance between it and what is running now is the whole problem in one page.
What comes back: which bots to keep and which to retire, the processes worth redesigning before re-automating, the register and standards to put in place, and a realistic order of work. Sometimes the first recommendation is to build nothing for a month and clear the maintenance backlog instead.
What you bring: access to the orchestrator or whatever inventory exists, and one person on the business side who can decide what a process is supposed to do. That second one matters more, because most of the decisions on this page are business decisions wearing technical clothes.
What we leave behind: a smaller, better-understood estate, a register with owners against it, standards the next developer can follow, and a team that can run it without us.
Our RPA automation services cover the build as well, but if your programme is stuck the build is rarely where we start.
Tell us what is stuck — the pilot that never scaled, the queue nobody is clearing, or the savings nobody can evidence. Let's Connect.
Frequently asked questions about RPA implementation challenges
What are the main challenges in RPA implementation?
Twelve, and they arrive in a predictable order. Before you build: choosing the wrong process, automating something undocumented, and having no business owner. During the first build: exceptions, credentials and screen-based automation. At scale: maintenance load, governance and licensing. After go-live: resistance, orphaned bots and measuring the benefit. The later ones are mostly earlier decisions arriving.
Why do RPA projects fail?
Rarely because the technology does not work. They fail because a bot depends on software nobody told you was changing, because bots fail quietly rather than loudly, and because RPA is bought as a project and lived with as an operation. The maintenance that nobody budgeted for is the most common single cause.
Which processes should we automate first?
High volume, stable, rule-based, with structured inputs and a named person who handles exceptions. Run that as a five-question test and drop anything failing the first three. Resist choosing the process somebody complains most about, because painful and valuable are not the same thing.
How do we scale RPA beyond a pilot?
Budget maintenance capacity from the first bot, keep a register of every automation with an owner against it, publish a rule about who may build what, and model licensing at the bot count you are aiming for. Most programmes stall at this point because the pilot proved the technology and nothing established the operating model.
Who should own RPA in an enterprise?
Each automated process needs a named owner in the business who decides what the bot does and what happens to exceptions. A central team — often called a centre of excellence — owns the standards, the register and the shared components. Ownership by IT alone is the arrangement that produces bots nobody will vouch for.
How much maintenance does a bot need?
More than the business case assumed, and it depends on what the bot touches rather than on its complexity. A bot driving three third-party screens will break more often than a complex one using a stable interface. Count breakages per bot per quarter for your own estate; it is the only number that reflects your applications.
What is an RPA centre of excellence?
Four practical things rather than a committee: a register of every automation with owners, development standards so any developer can pick up any bot, a library of reusable components, and one queue where requests are assessed and prioritised. At a smaller organisation this can be two people and a shared document.