A finding is not a task. It is a written statement that a control did not work, and it closes when somebody outside your team can see that the control now does.
That difference explains most of what goes wrong afterwards. A team reads the finding as a job, does the job, and reports it fixed, then the auditor comes back, asks for evidence covering the period, and the finding stays open. Nobody was careless, and the two sides were simply answering different questions.
Every article on common IT audit findings gives you the same list: access control, patch management, change management, backups. The list is accurate, and it is also the easy part. What none of them tell you is why the same items appear on your report year after year, what an auditor accepts as closure, and how to write the response that goes back with the report.
This page covers the findings you are most likely to see, the reason they repeat, and the procedure that closes one properly. It is written for the person who has just been handed a findings list and a deadline.
If you want the argument for why IT audits are worth running at all, our post on why IT audits matter for compliance makes that case, and this page assumes you are past it. At 4Labs Technologies we work through findings lists with clients, and the work is almost never the technical fix.
What an IT Audit Finding Actually Is
Before the list, settle the object. Most of the damage comes from teams treating an IT audit finding as a bug report.
Finding, Observation and Exception Are Not the Same Thing
Three words appear in audit reports and they carry different weight.
An audit finding says a control is missing, badly designed, or not operating. It goes in the report, it needs a management response, and somebody has to close it. Most reports pair each finding with a recommendation, and that recommendation is the auditor's suggestion rather than your plan, so you are free to close the gap a different way if you can evidence it.
An observation says something could be better but no control failed. It is advice. It does not need a remediation plan, and a team that treats every observation as a finding will spend the year on the wrong work.
An exception is a single instance where the control did not operate. Three exceptions out of forty samples may be reported as one finding about the control, or as three exceptions with no finding at all. The judgement sits with the auditor.
Read the wording before you plan anything. The control was not operating effectively during the period is a finding about design or operation. We noted that documentation could be improved is an observation with a different price.
The Risk Rating Decides Everything That Happens Next
Every finding carries a risk rating: high, medium, low, or a scale with more steps. That rating is not decoration, because it sets your deadline, the seniority of the person who has to respond, and whether the finding reaches a board or committee.
The rating comes from two things: how badly the control failed, and what it protects. A gap in access control on a system holding regulated data rates higher than the same gap on an internal wiki, and the failure is identical in both cases.
It is legitimate to discuss a rating with the auditor while the report is still in draft, and it is the only time you can. Do it with facts about the system rather than with feelings about the wording. A compensating control the auditor did not know about is a reason to move a rating. Being annoyed is not.
Once the report is issued, the rating is fixed and you are working to its deadline.
Why "We Have Fixed It" Does Not Close a Finding
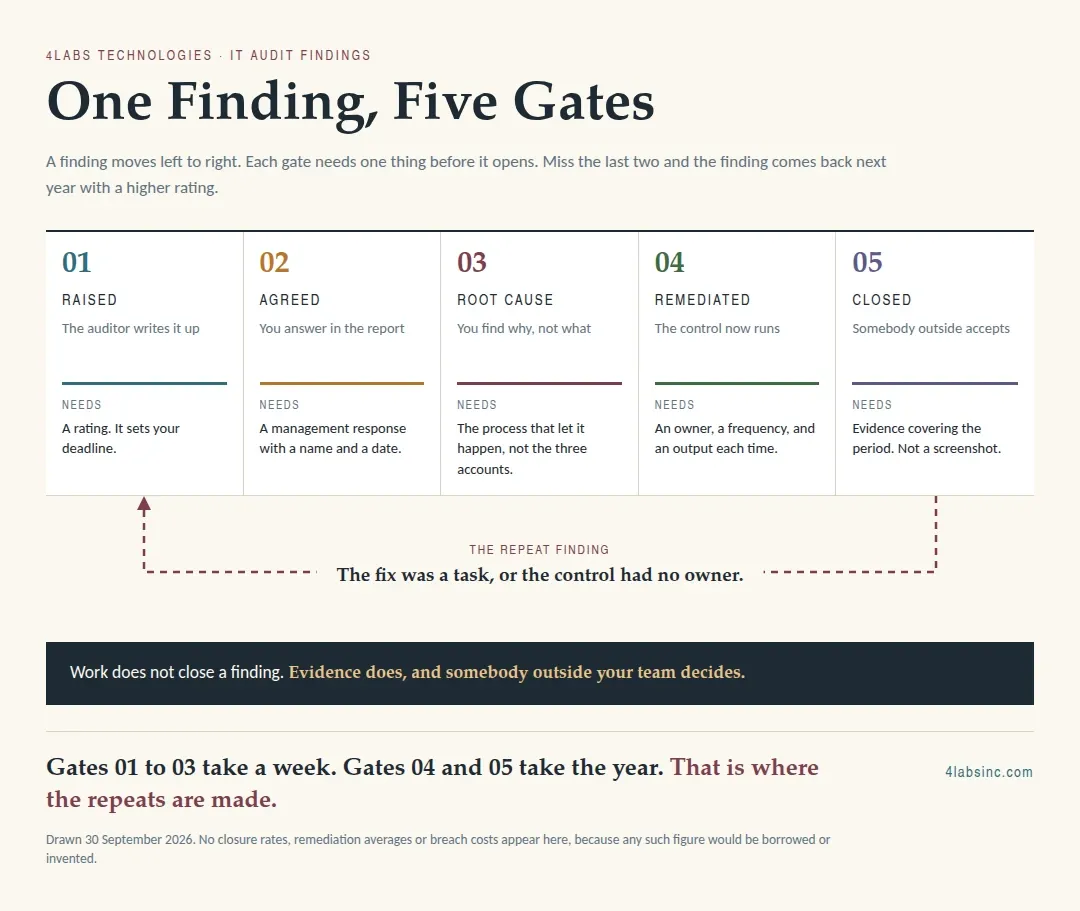
Here is the sentence that costs teams the most time: the fix is not the closure.
An auditor closes a finding on evidence. Not on your word, not on a screenshot of the current screen, and not on a ticket marked done. Evidence has to show that the control operated, over a period, and that somebody was responsible for it operating.
The Common IT Audit Findings That Come Up Most
Eight areas produce most of what lands in an IT audit report. The technical fix for each is usually known. The finding survives because the control has no rhythm and no owner.
Access Control: Joiners, Movers and the Leavers Nobody Removed
The most reported finding in IT audit, across every sector.
Auditors sample the user list and compare it with the people who work there. What they find is familiar: accounts belonging to people who left months ago, accounts belonging to people who moved to another department and kept both sets of rights, and contractor accounts nobody has looked at since the contract ended.
The leaver case is the one that gets written up hardest, because it is the clearest evidence that a process did not run. The mover case is the quieter problem. Rights accumulate, nobody revokes anything, and after three internal moves a person can approve their own work.
What closes it is a user access review that actually happens on a schedule, with the manager of each team confirming their own list, and a record of who confirmed what and when. The technical part is easy. The part that fails is somebody chasing eleven managers for replies every quarter.
If your joiner and leaver process depends on somebody remembering to email IT, the finding will come back. Tie account creation and removal to the event that already gets recorded reliably, which is usually payroll or the HR system.
Privileged Access and the Shared Admin Account
Administrator rights get their own finding because the damage from misuse is different in kind.
Three patterns come up. Too many people hold privileged access, usually because it was granted for a project that ended. Administrator accounts are shared, so nothing can be traced to a person. And privileged activity is not logged separately from ordinary activity, so nobody can review it even in principle.
Least privilege is the principle, and it is easy to state and awkward to apply. Start from what each person needs this month rather than what they were given when they joined. Where somebody needs elevated rights occasionally, grant them for the task and take them back, rather than leaving the rights in place because the request is tedious.
Shared accounts are worth a separate push. Even where the technical platform makes individual accounts difficult, a log of who used the shared account and when, kept at the time, turns an untraceable control into a traceable one.
Why the Same IT Audit Findings Repeat Every Year
A repeat audit finding is the most expensive line in any report. It rates higher than the original, it reaches people the original never did, and it says something about management rather than about technology. Three causes produce nearly all of them.
The Fix Was a Task, Not a Control
The finding said quarterly access reviews were not performed, the team performed an access review, and the finding closed.
Nine months later nobody has performed another one, because what was created was a task, not a control. A task happens once and ends, while a control has a frequency, an owner, a record, and somebody who notices when it does not happen.
This is the single most common reason a closed finding comes back, and it is visible at the time if you look. Read your own remediation plan and ask what happens in month seven. If the answer depends on somebody remembering, it is a task wearing a control's clothes.
The repair is small. Put the recurrence in whatever system already runs your work, name the person, and define what evidence the run produces. A calendar entry with no output is not enough, because at the next audit you have nothing to hand over.
Nobody Owns the Control Between Audits
The second cause is ownership, and it is usually mistaken for a resourcing problem.
During remediation a team forms around the finding. Somebody drives it, people attend the calls, the work gets done, and then the report closes and the group dissolves. The control still needs running, and nobody has it in their objectives.
A control owner is a named person who is answerable for the control operating, not for doing every part of it. They do not have to be senior. They do have to know they own it, which is a surprisingly common gap: ask three people who owns user access reviews and you will often get three answers, two of them wrong.
Where no owner can be named because the capacity does not exist, that is a resourcing finding to escalate rather than a documentation problem to write around. Say it plainly in the response. An unowned control is a repeat finding with a date on it.
Evidence Is Collected the Week Before
The third cause is a rhythm problem, and it produces findings that are technically unfair and still valid.
The control may have operated all year, but if the evidence is assembled in the week before fieldwork, from memory and from screenshots taken now, the auditor cannot test a period. What they see is a reconstruction, and a reconstruction fails.
Evidence should be a by-product of the control running, created at the time, and stored where it is produced. The review leaves a signed record, the change leaves an approval, and the restore test leaves a report. None of these are extra work if they are built into the step that already happens.
How to Address an IT Audit Finding, Step by Step
Audit finding remediation is four steps, in order, and skipping the first is what makes the other three take twice as long.
Agree the Finding Before You Argue With It
The management response is the written reply that goes into the report next to the finding. It is the first thing a reader sees after the finding itself, and it is read by people who will never read your remediation plan.
A response has three parts: whether you accept the finding, what you will do, and who will do it by when.
Accepting is usually right, and it is not a confession. Disputing a finding is legitimate where the auditor has the facts wrong or missed a compensating control, and in that case give the evidence rather than the objection. What damages you is a response that half accepts, argues in the margins, and commits to nothing. Auditors read that as a control that will still be broken next year, and they are usually right.
Write the response in plain sentences. We accept this finding, and quarterly access reviews will be reinstated from Q1, owned by the IT manager, with the first review completed by 31 March. That sentence answers every question a reader has, and a paragraph about the complexity of the estate does not.
One trap: do not commit to a date the team has not agreed to. The response is a public commitment with your name against it, and a missed date becomes its own finding.
Find the Root Cause, Not the Instance
The auditor sampled, the finding names what the sample showed, and the sample is not the problem.
Three leaver accounts were still active. Removing those three accounts takes ten minutes and closes nothing, because the question is why the process did not remove them. Was IT never told? Was there no list to check against? Did the request arrive and go unactioned?
Each of those has a different root cause and a different repair. The first is a handover problem between HR and IT, the second is missing data, and the third is a queue nobody watches. Fix the wrong one and the finding repeats with different account names.
Ask why until the answer stops being about people and starts being about the process. Not because people are blameless, but because a process that depends on nobody ever forgetting is the actual finding.
Where the root cause sits outside your team, say so in the plan and name the other team. A finding that needs HR to change a process cannot be closed by IT alone, and pretending otherwise guarantees the repeat.
Write the Corrective Action Plan: Owner, Date, Evidence
How to Stop Findings Before the Next Audit
Audit readiness is not a project that runs in the month before fieldwork. It is three habits that make the audit uneventful.
Run the Control Yourself, on a Schedule
Pick your five most audited controls and test them yourself, once a quarter, the way an auditor would.
Sample ten users and check their rights against their job. Pick five production changes and look for the approval. Take one system and ask when it was last patched. Restore one backup. Read a week of privileged access logs.
Half a day, and it tells you what your report will say months before the report exists. What you find, you fix quietly. What you cannot fix, you escalate early with a plan already attached, which is a completely different conversation from being told by an auditor.
This is internal audit thinking applied by the team that runs the systems. It does not replace independent assurance, and it removes most of the surprises from it.
Keep Evidence Where It Is Generated
The second habit is storage, and it is duller and more valuable than it sounds.
Every control that runs should leave its output in one known place, at the time, named so that somebody else can find it. The access review goes to the same folder every quarter. The restore test report goes next to the last one. The policy approval sits with the policy.
When fieldwork starts, compliance evidence becomes a matter of pointing at a folder rather than a fortnight of archaeology. That saves the team a fortnight and it removes the incentive to reconstruct, which is where the reconstruction findings come from.
One rule to hold: no personal drives, no private mailboxes. Evidence that lives with one person leaves when they do, and then a control that ran for three years cannot be shown to have run at all.
Walk the Controls Before the Auditor Does
A few weeks before fieldwork, walk each control with the person who owns it and ask three questions. What exactly do you do. Show me the last time you did it. What would happen if you were away that week.
The third question finds more information security gaps than the other two together, because it exposes controls that depend on one person being present. The second question finds evidence that does not exist. The first finds the drift between what the documentation says and what is really done, which is almost always in the documentation's favour.
Where a walkthrough finds a gap, you have two honest options: fix it, or write it into the response before the auditor writes it into the report. Raising something yourself changes how it lands. It reads as a control environment that knows itself, and that impression carries into every other judgement the auditor makes.
Quick Answers on IT Audit Findings
Short answers to the questions people type first, each one standing alone.
What Is an IT Audit Finding?
An IT audit finding is a written statement that a control was missing, badly designed, or not operating during the period under review. It carries a risk rating, it needs a management response naming an owner and a date, and it stays open until evidence shows the control now works. It is different from an observation, which is advice with no control failure behind it, and from an exception, which is one instance rather than a conclusion about the control.
What Are the Most Common IT Audit Findings?
The ones that appear most often are user access findings such as leaver accounts still active and rights that accumulated after internal moves, privileged access held too widely or shared between people, patch management running slower than the organisation's own policy, production changes made without approval or without test evidence, backups that were never restored as a test, logs collected but never reviewed, third-party suppliers never assessed after onboarding, and security policies that are out of date or unread. Segregation of duties is a near-certain finding in small teams.
How Do You Respond to an IT Audit Finding?
Accept the finding unless you have evidence it is factually wrong, then write a management response with three parts: what you will do, who owns it by name, and the completion date. Behind that, build a corrective action plan that addresses the root cause rather than the sampled instances, and decide at planning time what evidence will exist afterwards. Do not commit to a date the team has not agreed, because a missed remediation date becomes a finding of its own.
What Is a Repeat Audit Finding?
A repeat audit finding is one raised again after it was previously reported or closed. It usually rates higher than the original because it points at management action rather than at a technical gap, and it often reaches a board or audit committee that never saw the first version. The three usual causes are a fix that was a one-off task rather than a recurring control, a control with no named owner between audits, and evidence assembled just before fieldwork instead of produced as the control runs.
How Long Should Remediation Take?
The deadline comes from the risk rating and is agreed with whoever issued the report, so it is set case by case rather than by a general rule. High-rated findings are normally expected to move quickly and low-rated ones can align with a planned change. What matters more than the length is that the date is realistic and agreed by the person who owns the work. Where the full repair is long, split it into an interim control that reduces the risk now and a permanent one with its own date, and write both into the plan.
Close the Findings You Already Have
Every organisation has a findings list from last time. The useful question is not what is on it. It is how many items carry the same date, the same owner, and the same wording as last year.
If that describes your list, talk to 4Labs Technologies. Bring last year's findings and the closure dates against each one. Where a date has moved twice, the control has an owner problem rather than a technical one, and that is a different piece of work from the one the report describes.
Our cybersecurity consulting services team works the order in this article: agree the finding, find the root cause, then produce evidence somebody outside the team will accept.